Certified-Data-Engineer-Professional認證考試解析, Certified-Data-Engineer-Professional考題套裝, Certified-Data-Engineer-Professional權威考題, 最新Certified-Data-Engineer-Professional考題, 最新Certified-Data-Engineer-Professional題庫資訊

對於為了進入大中型IT公司的畢業生來說,不想花費太多的錢去補習,只能借助於最新的 Testpdf Certified-Data-Engineer-Professional 考題准備考試,因為這類考題在網路中的價錢不是很高。我們會持續不斷從世界各地使用者在他們的地區參加 Databricks 考試而獲得回饋,輕鬆的了解最新考試資訊,及時的更新 Certified-Data-Engineer-Professional 題庫,這使我們的其他用戶可以共用這些考試資訊,參加考試更有信心!這是通過 Certified-Data-Engineer-Professional 考試最有效的方法之一。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section |
Objectives |
| Topic 1: Monitoring and Alerting |
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Query Profiler and Spark UI to monitor workloads
|
| Topic 2: Developing Code for Data Processing using Python and SQL |
- Building and Testing ETL Pipelines
- 1. Compare streaming tables and materialized views
- 2. Use APPLY CHANGES APIs for change data capture
- 3. Develop unit and integration tests for data processing code
- 4. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 5. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 6. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 7. Use control flow operators in pipeline components
- 8. Configure environments, dependencies, memory, and retry behavior
- Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Topic 3: Cost & Performance Optimisation |
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Topic 4: Data Ingestion & Acquisition |
- Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
| Topic 5: Data Governance |
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 6: Debugging and Deploying |
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Analyze errors and remediate failed job runs
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Topic 7: Data Sharing and Federation |
- Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 8: Data Transformation, Cleansing, and Quality |
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Topic 9: Ensuring Data Security and Compliance |
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
- Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
|
| Topic 10: Data Modelling |
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake
|
>> Certified-Data-Engineer-Professional認證考試解析 <<
免費下載Certified-Data-Engineer-Professional認證考試解析和資格考試中的領先供應商和值得信賴的Certified-Data-Engineer-Professional考題套裝
為了每位IT認證考試的考生切身利益,我們網站提供Testpdf Databricks的Certified-Data-Engineer-Professional考試培訓資料是根據考生的需要而定做的,由我們Testpdf資質深厚的IT專家專門研究出來的,他們的奮鬥結果不僅僅是為了幫助你們通過考試,而且是為了讓你們有一個更好的明天。
最新的 Databricks Certification Certified-Data-Engineer-Professional 免費考試真題 (Q172-Q177):
問題 #172
A table in the Lakehouse named customer_churn_params is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
- A. Apply the churn model to all rows in the customer_churn_params table, but implement logic to perform an upsert into the predictions table that ignores rows where predictions have not changed.
- B. Replace the current overwrite logic with a merge statement to modify only those records that have changed; write logic to make predictions on the changed records identified by the change data feed.
- C. Calculate the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers before making new predictions; only make predictions on those customers not in the previous predictions.
- D. Convert the batch job to a Structured Streaming job using the complete output mode; configure a Structured Streaming job to read from the customer_churn_params table and incrementally predict against the churn model.
- E. Modify the overwrite logic to include a field populated by calling
spark.sql.functions.current_timestamp() as data are being written; use this field to identify records written on a particular date.
答案:B
解題說明:
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed.
This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
問題 #173
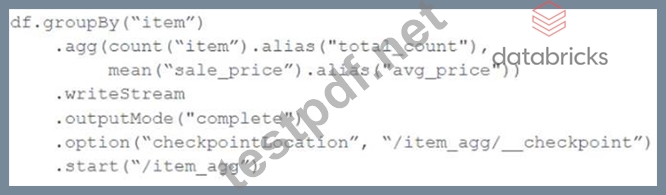
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query:
Proposed query:
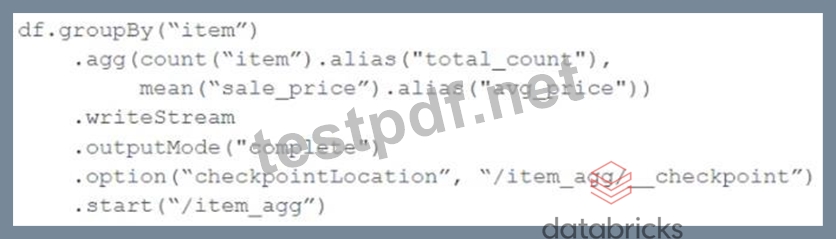
Which step must also be completed to put the proposed query into production?
- A. Increase the shuffle partitions to account for additional aggregates
- B. Remove .option (mergeSchema', true') from the streaming write
- C. Run REFRESH TABLE delta, /item_agg'
- D. Specify a new checkpointlocation
- E. Register the data in the "/item_agg" directory to the Hive metastore
答案:D
解題說明:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
問題 #174
Incorporating unit tests into a PySpark application requires upfront attention to the design of your jobs, or a potentially significant refactoring of existing code.
Which statement describes a main benefit that offset this additional effort?
- A. Ensures that all steps interact correctly to achieve the desired end result
- B. Validates a complete use case of your application
- C. Yields faster deployment and execution times
- D. Troubleshooting is easier since all steps are isolated and tested individually
- E. Improves the quality of your data
答案:D
解題說明:
Unit tests are small, isolated tests that are used to check specific parts of the code, such as functions or classes.
問題 #175
A data engineer is brining an existing production Databricks job under asset bundle management and wants to ensure that:
- The job's current configuration is captured as YAML, and all
referenced files are included in their bundle project.
- Future changes to the bundle's YAML will update the existing job in-
place (not create a new job)
How should the data engineer successfully move the production job under asset bundle management?
- A. Manually create the YAML configuration for the job in your bundle project, ensuring all settings match the existing job. Then, run Databricks bundle deploy the bundle, which will update the existing job in your workspace.
- B. Run Databricks bundle generate job --existing-job-id to generate the YAML and download referenced files. Then, run Databricks bundle deploy to deploy the bundle, which will always update the existing job automatically.
- C. Export the job definition as JSON, convert it to YAML, and place it in your bundle. Then, run Databricks bundle deploy to update the existing job.
- D. Run databricks bundle generate job --existing-job-id to generate the YAML and download referenced files. Then, run Databricks bundle deployment, bind to link the bundle's job resource to the existing job in Databricks.
答案:D
解題說明:
Generating the bundle from the existing job captures the full job configuration as YAML and pulls in all referenced files into the bundle project. Binding the generated job resource to the existing Databricks job establishes a persistent link, ensuring that future bundle deployments update the same production job in place rather than creating a new one.
問題 #176
The business intelligence team has a dashboard configured to track various summary metrics for retail stories. This includes total sales for the previous day alongside totals and averages for a variety of time periods. The fields required to populate this dashboard have the following schema:

For Demand forecasting, the Lakehouse contains a validated table of all itemized sales updated incrementally in near real-time. This table named products_per_order, includes the following fields:

Because reporting on long-term sales trends is less volatile, analysts using the new dashboard only require data to be refreshed once daily. Because the dashboard will be queried interactively by many users throughout a normal business day, it should return results quickly and reduce total compute associated with each materialization.
Which solution meets the expectations of the end users while controlling and limiting possible costs?
- A. Define a view against the products_per_order table and define the dashboard against this view.
- B. Configure a webhook to execute an incremental read against products_per_order each time the dashboard is refreshed.
- C. Use the Delta Cache to persists the products_per_order table in memory to quickly the dashboard with each query.
- D. Use Structure Streaming to configure a live dashboard against the products_per_order table within a Databricks notebook.
- E. Populate the dashboard by configuring a nightly batch job to save the required values as a table overwritten with each update.
答案:E
問題 #177
......
在這個人才濟濟的社會,人們不斷提高自己的知識想達到更高的水準,但是國家對尖端的IT人員需求量還在不斷擴大,國際上更是如此。所以很多人想通過Databricks的Certified-Data-Engineer-Professional考試認證,但想通過並非易事。其實只要你們選擇一個好的培訓資料完全通過也不是不可能,我們Testpdf Databricks的Certified-Data-Engineer-Professional考試認證培訓資料完全擁有這個能力幫助你們通過認證,Testpdf網站的培訓資料是通過許多使用過的考生實踐證明了的,而且在國際上一直遙遙領先,如果你要通過Databricks的Certified-Data-Engineer-Professional考試認證,就將Testpdf Databricks的Certified-Data-Engineer-Professional考試認證培訓資料加入購物車吧!
Certified-Data-Engineer-Professional考題套裝: https://www.testpdf.net/Certified-Data-Engineer-Professional.html
- Certified-Data-Engineer-Professional考試內容 ♿ Certified-Data-Engineer-Professional考題 🧹 Certified-Data-Engineer-Professional更新 🏨 複製網址➠ www.vcesoft.com 🠰打開並搜索▛ Certified-Data-Engineer-Professional ▟免費下載Certified-Data-Engineer-Professional真題
- Certified-Data-Engineer-Professional熱門認證 🧩 新版Certified-Data-Engineer-Professional考古題 🦪 Certified-Data-Engineer-Professional熱門認證 🤡 在⏩ www.newdumpspdf.com ⏪網站上查找➽ Certified-Data-Engineer-Professional 🢪的最新題庫Certified-Data-Engineer-Professional題庫更新
- 最有效的Certified-Data-Engineer-Professional認證考試解析-最新考試題庫幫助妳壹次性通過考試Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional 🔮 《 www.pdfexamdumps.com 》提供免費“ Certified-Data-Engineer-Professional ”問題收集Certified-Data-Engineer-Professional考試大綱
- Certified-Data-Engineer-Professional題庫更新 🐠 新版Certified-Data-Engineer-Professional考古題 🏗 Certified-Data-Engineer-Professional考試資訊 ⬅️ 來自網站▷ www.newdumpspdf.com ◁打開並搜索▷ Certified-Data-Engineer-Professional ◁免費下載Certified-Data-Engineer-Professional考試資訊
- 我們提供最有效的Certified-Data-Engineer-Professional認證考試解析,保證妳100%通過考試 💘 在⮆ www.newdumpspdf.com ⮄網站下載免費⏩ Certified-Data-Engineer-Professional ⏪題庫收集Certified-Data-Engineer-Professional熱門認證
- 更新的Databricks Certified-Data-Engineer-Professional認證考試解析是行業領先材料&有效的Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional 🦅 透過【 www.newdumpspdf.com 】搜索{ Certified-Data-Engineer-Professional }免費下載考試資料Certified-Data-Engineer-Professional題庫分享
- 精準的Certified-Data-Engineer-Professional認證考試解析,最有效的考試題庫幫助妳快速通過Certified-Data-Engineer-Professional考試 🗳 免費下載⇛ Certified-Data-Engineer-Professional ⇚只需在⇛ www.newdumpspdf.com ⇚上搜索Certified-Data-Engineer-Professional測試
- Certified-Data-Engineer-Professional考古題分享 🚒 Certified-Data-Engineer-Professional權威認證 🕶 Certified-Data-Engineer-Professional真題 🐃 立即打開▷ www.newdumpspdf.com ◁並搜索[ Certified-Data-Engineer-Professional ]以獲取免費下載Certified-Data-Engineer-Professional最新題庫
- 最受推薦的Certified-Data-Engineer-Professional認證考試解析,免費下載Certified-Data-Engineer-Professional考試指南得到妳想要的Databricks證書 🐥 在{ www.pdfexamdumps.com }網站下載免費▶ Certified-Data-Engineer-Professional ◀題庫收集Certified-Data-Engineer-Professional題庫更新
- Certified-Data-Engineer-Professional考古題分享 🐷 Certified-Data-Engineer-Professional證照 😊 Certified-Data-Engineer-Professional考古題分享 🚤 開啟[ www.newdumpspdf.com ]輸入➽ Certified-Data-Engineer-Professional 🢪並獲取免費下載Certified-Data-Engineer-Professional證照信息
- 我們提供最有效的Certified-Data-Engineer-Professional認證考試解析,保證妳100%通過考試 🥜 開啟➥ tw.fast2test.com 🡄輸入( Certified-Data-Engineer-Professional )並獲取免費下載Certified-Data-Engineer-Professional測試
-
www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, telegra.ph, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes


 icons at the top
right corner of the subsection.