AI-300學習筆記, 最新AI-300考古題, AI-300認證考試, 免費下載AI-300考題, AI-300考題寶典

NewDumps的AI-300考古題有两种版本,即PDF版和软件版。這樣可以給你最大的方便。PDF版方便你的使用,你可以下載並且將AI-300考古題列印出來以供隨時學習。軟體版類比了真實的考試,可以讓你切身感受到Microsoft考試的氣氛。这样在考试时你就可以轻松自如地应对了。
Microsoft AI-300 Exam Syllabus Topics:
| Section |
Weight |
Objectives |
| Topic 1: Optimize generative AI systems and model performance |
15–20% |
- Improve efficiency and cost-effectiveness
- 1. Optimize inference and deployment
- 2. Manage resource utilization
- Optimize model selection and configuration
- 1. Tune prompts and generation settings
- 2. Choose appropriate models and parameters
|
| Topic 2: Implement machine learning model lifecycle and operations |
25–30% |
- Deploy models to production
- 1. Configure deployment options and scaling
- 2. Deploy to real-time and batch endpoints
- Orchestrate model training and experimentation
- 1. Create and manage pipelines
- 2. Track experiments and metrics
- Register, version, and package models
- 1. Manage model registry
- 2. Create reusable model packages
- Monitor and maintain models in production
- 1. Implement retraining and update workflows
- 2. Monitor data and model drift
|
| Topic 3: Design and implement an MLOps infrastructure |
15–20% |
- Implement infrastructure as code for Machine Learning
- 1. Use Bicep or Azure CLI to deploy resources
- 2. Automate infrastructure provisioning
- Create and manage Machine Learning workspace resources and assets
- 1. Configure workspace settings and security
- 2. Manage compute targets, datastores, and environments
|
| Topic 4: Design and implement a GenAIOps infrastructure |
20–25% |
- Implement infrastructure for generative AI workloads
- 1. Integrate with Azure services and tools
- 2. Design scalable and secure architecture
- Set up Microsoft Foundry environment
- 1. Manage compute and deployment resources
- 2. Configure projects, connections, and security
|
| Topic 5: Implement generative AI quality assurance and observability |
10–15% |
- Monitor generative AI systems
- 1. Implement logging and alerting
- 2. Track usage, performance, and errors
- Evaluate and test generative AI applications
- 1. Define evaluation metrics and criteria
- 2. Test for safety, accuracy, and relevance
|
>> Microsoft AI-300學習筆記 <<
高通過率的Microsoft AI-300學習筆記是行業領先材料&可靠的AI-300:Operationalizing Machine Learning and Generative AI Solutions
你想过怎么样才能更轻松地通过Microsoft的AI-300认证考试吗?你发现诀窍了吗?如果你不知道怎么办的话,我来告诉你。其實通過考試的方法有很多種。努力學習考試要求的所有的相關知識就是其中的一種方法。你現在正在這樣做嗎?但是這是最浪費時間並且很可能得不到預期的效果的方法。而且,每天都忙於工作的你恐怕沒有那麼多時間來準備考試吧?那麼試一下NewDumps的AI-300考古題吧。這個資料絕對可以讓你得到你想不到的成果。
最新的 Microsoft Certified AI-300 免費考試真題 (Q48-Q53):
問題 #48
A data science team completes multiple training runs within an experiment by using MLflow.
The team wants to store a selected model in Azure Machine Learning so that it can be versioned and deployed later.
The model must be versioned centrally for reuse across environments.
You need to version the trained model.
Which two actions should you perform? Each correct answer presents part of the solution.
Choose two.
NOTE: Each correct selection is worth one point.
- A. Export the model files to local storage.
- B. Register the model in the Azure Machine Learning workspace.
- C. Locate and capture the model artifacts from the outputs of the training run.
- D. Tag the training experiment with a name.
答案:B,C
解題說明:
To set up versioning for a trained model in an Azure Machine Learning (Azure ML) workspace using MLflow, you must capture the model artifacts during the training run and then register the model into the centralized registry.
[A]
1. Capture Model Artifacts
During each training run, use the MLflow SDK to log the model. This ensures that all necessary files (the model binary, environment dependencies, and the MLmodel metadata) are stored as run outputs in the workspace.
Manual Logging: Use a flavor-specific method like mlflow.sklearn.log_model(model,
"model_path") within an active run.
Automatic Logging: Call mlflow.autolog() before starting your training. This automatically captures metrics, parameters, and the model artifacts for supported frameworks.
Artifact Location: Once logged, artifacts are typically found in the outputs/ folder of the specific run, accessible via the Azure Machine Learning Studio.
[B]
2. Register the Model
After identifying the best-performing run, you register it to the Model Registry. This creates a named, versioned entity that can be accessed across different environments for deployment.
To set up versioning for an MLflow model in Azure Machine Learning (Azure ML) that is accessible across different environments, you should use a centralized Azure ML Registry. While a standard Azure ML Workspace acts as an MLflow server for individual experiments, an Azure ML Registry is the specifically designed feature for sharing models, environments, and components across multiple workspaces and environments within an Azure tenant.
3. Centralized Reuse
By registering the model in the workspace's registry, you establish a single source of truth. You can then load this specific version in any environment (e.g., staging or production) using its registry URI: models:/<model_name>/<version_or_alias>.
Incorrect:
[Not D]
Must use an Azure ML Registry (Central).
Reference:
https://mlflow.org/docs/latest/ml/model-registry/
問題 #49
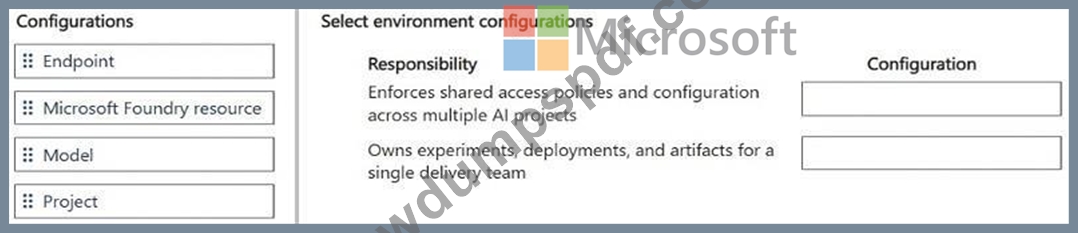
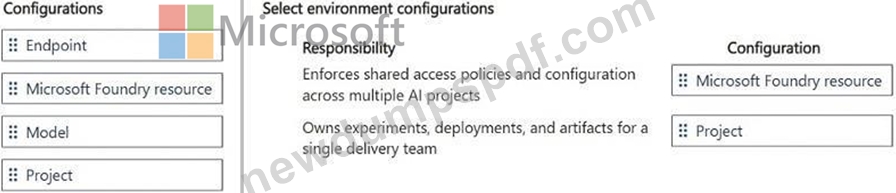
Drag and Drop Question
An organization is adopting Microsoft Foundry to support multiple generative AI projects across different teams. Microsoft Foundry platform administrators require centralized governance.
Development teams need isolated environments for experimentation and deployment.
Shared policies must be enforced consistently while allowing teams to work independently.
You need to configure the Microsoft Foundry environment to meet the requirements.
Which Microsoft Foundry components should you configure? To answer, move the appropriate configurations to the correct responsibilities. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
答案:
解題說明:
問題 #50
An organization maintains separate Azure Machine Learning workspaces for development and production.
Both environments must use the same validated assets without duplicating them.
Assets must be shared across workspaces while maintaining centralized governance and version control.
You need to enable reuse of assets across workspaces without copying them.
What should you do?
- A. Publish the asset to an Azure Machine Learning registry.
- B. Publish the asset as a pipeline component.
- C. Enable workspace-level Git integration and sync assets between repositories.
- D. Create a shared Azure Machine Learning environment that includes the asset.
答案:A
解題說明:
To share validated assets between development and production workspaces while maintaining centralized governance and version control, you should use Azure Machine Learning Registries.
Microsoft Learn
Unlike standard workspaces, registries are workspace-agnostic. They act as a central catalog that decouples assets from individual environments, allowing you to "promote" a model or environment from Dev to Prod without manual duplication or data drift.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-machine-learning-registries- mlops
問題 #51
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage a Retrieval-Augmented Generation (RAG) application built on Microsoft Foundry.
The application retrieves documents from an indexed knowledge base and generates answers for internal users.
Recent feedback indicates that answers are fluent but sometimes include information that is not supported by the documents that were retrieved.
You need to evaluate whether a proposed change improves RAG answer quality by using supported and measurable techniques.
Solution: Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Does the solution meet the goal?
答案:A
解題說明:
Correct:
* Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Relying solely on user feedback comments is not the proper immediate action for evaluating this specific issue but it is still the best choice.
Evaluate whether your proposed change improves the Retrieval-Augmented Generation (RAG) system by reducing hallucinations (unsupported information), you need to measure faithfulness and context relevance using automated, quantifiable metrics.
The proper course of action is to implement an LLM-as-a-Judge framework using an open-source evaluation library like Ragas or TruLens.
Recommended Evaluation Plan
Establish a baseline: Run your current RAG pipeline through a test dataset of 50-100 representative user queries.
Capture the outputs: Save the user query, the exact retrieved document snippets, and the generated response for every test.
Apply the change: Deploy your proposed modification (e.g., altered prompt, different temperature, or re-ranking algorithm).Run the evaluation: Pass the test dataset through the updated pipeline to generate a new set of responses.
Compare the metrics: Use the framework to score both sets of data and mathematically verify if the change reduced unsupported claims.
Incorrect:
* Compare embedding vector dimensions used by the retrieval pipeline before and after the change.
Comparing embedding vector dimensions is not a valid or effective method for measuring RAG answer quality. Vector dimensions (e.g., 1536 or 3072) are static architectural properties of your embedding model. They do not reflect factual accuracy, semantic grounding, or the rate of hallucinations in your text generation.
* Measure token throughput and average response latency before and after applying the proposed change.
Measuring token throughput and latency is not the correct action to solve this specific problem.
Reference:
https://www.getmaxim.ai/articles/how-to-evaluate-your-rag-system/
問題 #52
A company's platform engineers manage the resource settings and governance of Microsoft Foundry.
Developers must be able to create and update project assets but must not be able to change resource-level configurations.
You need to enforce least privilege access for the engineers and developers.
Which two actions should you perform? Each correct answer presents part of the solution.
Choose two.
NOTE: Each correct selection is worth one point.
- A. Share a single API key across all teams.
- B. Assign a resource-level Azure AI Administrator role to the platform engineers.
- C. Disable Microsoft Entra ID authentication for the Microsoft Foundry resource.
- D. Assign the Azure AI Developer role to the developers.
答案:B,D
解題說明:
[A]
Engineer Permissions (Hub Scope)
Engineers require the ability to manage infrastructure, networking, and global security settings.
Role: Azure AI Administrator or Contributor.
Assignment Scope: Assign at the Foundry Hub/Resource level.
Capabilities: They can manage virtual networks, customer-managed keys, and shared connections (e.g., Azure OpenAI) that all projects inherit.
[C]
Developer Permissions (Project Scope)
Developers should be restricted from changing the underlying resource configurations but need full access to their specific AI workloads.
Role: Azure AI Developer or Project Contributor.
Assignment Scope: Assign strictly at the Foundry Project level.
Capabilities: This allows them to create and update project assets (agents, flows, evaluations) and deploy models without permission to modify Hub-level infrastructure or security settings Reference:
https://learn.microsoft.com/en-us/azure/foundry/concepts/rbac-foundry
問題 #53
......
作為IT認證考試學習資料的專業團隊,NewDumps是您獲得高品質學習資料的來源。無論您需要尋找什么樣子的Microsoft AI-300考古題我們都可以提供,借助我們的AI-300學習資料,您不必浪費時間去閱讀更多的參考書,只需花費20 – 30小時掌握我們的Microsoft AI-300題庫問題和答案,就可以順利通過考試。我們為您提供PDF版本的和軟件版,還有在線測試引擎題庫,其中AI-300軟件版本的題庫,可以模擬真實的考試環境,以滿足大家的需求,這是最優秀的AI-300學習資料。
最新AI-300考古題: https://www.newdumpspdf.com/AI-300-exam-new-dumps.html
- AI-300考題寶典 🗯 AI-300題庫更新資訊 🔀 AI-300試題 🚠 《 www.newdumpspdf.com 》提供免費[ AI-300 ]問題收集AI-300參考資料
- 最受推薦的AI-300學習筆記,免費下載AI-300考試指南得到妳想要的Microsoft證書 🤷 開啟➡ www.newdumpspdf.com ️⬅️輸入「 AI-300 」並獲取免費下載AI-300證照
- AI-300熱門認證 🏃 AI-300下載 👞 AI-300熱門證照 🚼 複製網址【 tw.fast2test.com 】打開並搜索( AI-300 )免費下載AI-300熱門認證
- AI-300熱門考古題 🥦 AI-300考題寶典 🏵 AI-300最新考題 🏩 到“ www.newdumpspdf.com ”搜尋【 AI-300 】以獲取免費下載考試資料AI-300考題免費下載
- AI-300软件版 🚹 AI-300熱門考古題 🛴 AI-300最新考題 🧅 免費下載⮆ AI-300 ⮄只需在( www.testpdf.net )上搜索AI-300題庫更新資訊
- 最受推薦的AI-300學習筆記,免費下載AI-300考試指南得到妳想要的Microsoft證書 🛳 來自網站{ www.newdumpspdf.com }打開並搜索☀ AI-300 ️☀️免費下載AI-300參考資料
- AI-300試題 🅾 AI-300題庫更新資訊 🚪 AI-300最新試題 😾 透過➤ www.pdfexamdumps.com ⮘搜索▛ AI-300 ▟免費下載考試資料AI-300參考資料
- 優秀的AI-300學習筆記和資格考試中的領先提供商和快速下載AI-300:Operationalizing Machine Learning and Generative AI Solutions 🗓 立即在⇛ www.newdumpspdf.com ⇚上搜尋⏩ AI-300 ⏪並免費下載最新AI-300題庫資源
- AI-300學習筆記,最新AI-300考古題,AI-300認證考試 😚 { tw.fast2test.com }上的▶ AI-300 ◀免費下載只需搜尋AI-300下載
- 頂尖的AI-300學習筆記和資格考試中的領導者和全面覆蓋的Microsoft Operationalizing Machine Learning and Generative AI Solutions 🥫 透過「 www.newdumpspdf.com 」輕鬆獲取▷ AI-300 ◁免費下載AI-300最新考題
- AI-300熱門考題 🕶 AI-300熱門考古題 ⏪ AI-300題庫更新資訊 🟨 ⇛ www.newdumpspdf.com ⇚是獲取➥ AI-300 🡄免費下載的最佳網站AI-300題庫更新資訊
-
www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes


 icons at the top
right corner of the subsection.