Databricks-Certified-Data-Engineer-Associate인기자격증 덤프문제, Databricks-Certified-Data-Engineer-Associate최신버전 시험덤프문제, Databricks-Certified-Data-Engineer-Associate 100%시험패스 덤프문제, Databricks-Certified-Data-Engineer-Associate높은 통과율 인기덤프, Databricks-Certified-Data-Engineer-Associate최신 인증시험 공부자료
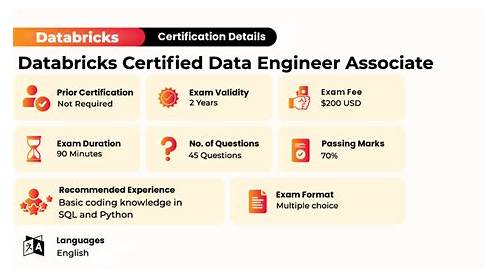
DumpTOP Databricks-Certified-Data-Engineer-Associate 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1-Vb5jDaEPPHY6La98fDa38D5-uazPWf3
우리DumpTOP 에서 제공하는 학습가이드에는 IT전문가들이 만들어낸 시험대비 자료들과Databricks Databricks-Certified-Data-Engineer-Associate인증시험의 완벽한 문제와 답들입니다. 그리고 우리DumpTOP에서는 IT업계에서의 높은 신뢰감으로 여러분들한테 100%보장을 드립니다. 우리에 믿음을 드리기 위하여Databricks Databricks-Certified-Data-Engineer-Associate관련자료의 일부분 문제와 답 등 샘플을 무료로 다운받아 체험해볼수 있게 제공합니다.
Databricks Databricks-Certified-Data-Engineer-Associate Exam Syllabus Topics:
| Section |
Weight |
Objectives |
| Delta Lake Fundamentals |
20-25% |
- Create and manage Delta tables
- Explain Delta Lake features and benefits
- Understand ACID transactions and time travel
- Write to and read from Delta tables
|
| Data Pipeline Architecture |
15-20% |
- Design data pipelines for batch and streaming
- Monitor and optimize pipeline performance
- Understand ELT vs ETL patterns
- Implement incremental data processing
|
| Apache Spark Data Processing Fundamentals |
20-25% |
- Create and use Spark DataFrames
- Work with structured data types (arrays, maps, structs)
- Apply transformations and actions on DataFrames
- Use Spark SQL for data processing
|
| Lakehouse Platform Concepts |
10-15% |
- Describe key Databricks Lakehouse platform components
- Explain data governance and security concepts
- Understand the Lakehouse architecture and its benefits
|
| Spark SQL and DataFrames |
15-20% |
- Handle null values and data quality
- Write and execute Spark SQL queries
- Aggregate and group data
- Join and union DataFrames
|
| Python for Data Engineering |
10-15% |
- Implement user-defined functions (UDFs)
- Use PySpark for data processing
- Work with Spark APIs in Python
|
>> Databricks-Certified-Data-Engineer-Associate인기자격증 덤프문제 <<
Databricks-Certified-Data-Engineer-Associate최신버전 시험덤프문제, Databricks-Certified-Data-Engineer-Associate 100%시험패스 덤프문제
DumpTOP는 몇년간 최고급 덤프품질로 IT인증덤프제공사이트중에서 손꼽히는 자리에 오게 되었습니다. Databricks Databricks-Certified-Data-Engineer-Associate 덤프는 많은 덤프들중에서 구매하는 분이 많은 인기덤프입니다. Databricks Databricks-Certified-Data-Engineer-Associate시험준비중이신 분이시라면Databricks Databricks-Certified-Data-Engineer-Associate한번 믿고 시험에 도전해보세요. 좋은 성적으로 시험패스하여 자격증 취득할것입니다.
최신 Databricks Certification Databricks-Certified-Data-Engineer-Associate 무료샘플문제 (Q302-Q307):
질문 # 302
A data engineer is developing a small proof of concept in a notebook. When running the entire notebook, cluster usage spikes. The data engineer wants to keep the development experience and get real-time results.
Which cluster meets these requirements?
- A. All-Purpose Cluster with autoscaling
- B. All-Purpose Cluster with a large fixed memory size
- C. Job Cluster with Photon enabled and autoscaling
- D. Job Cluster with autoscaling enabled
정답:A
설명:
For interactive notebook development, Databricks distinguishes between all-purpose compute and job compute. All-purpose compute is designed for analysis, notebook development, and interactive workloads, while job compute is intended for automated scheduled or triggered jobs. Because the engineer is actively developing a proof of concept in a notebook and wants real-time feedback, an all-purpose cluster is the right compute type. Adding autoscaling makes it better suited to the observed usage spikes, because the cluster can expand when notebook execution demands more resources and scale down afterward, reducing waste compared with a large fixed-size cluster. That makes option B the best answer. Option A keeps the interactive development model, but the fixed large size is less efficient. Options C and D use job clusters, which are better aligned with production jobs rather than iterative notebook-based development. Databricks documentation consistently positions all-purpose compute for collaborative and interactive development, and autoscaling is a standard mechanism to handle variable workloads more efficiently.
=========
질문 # 303
A data engineer has a Job with multiple tasks that runs nightly. Each of the tasks runs slowly because the clusters take a long time to start.
Which of the following actions can the data engineer perform to improve the start up time for the clusters used for the Job?
- A. They can use jobs clusters instead of all-purpose clusters
- B. They can use endpoints available in Databricks SQL
- C. They can use clusters that are from a cluster pool
- D. They can configure the clusters to be single-node
- E. They can configure the clusters to autoscale for larger data sizes
정답:C
질문 # 304
Which of the following commands will return the number of null values in the member_id column?
- A. SELECT null(member_id) FROM my_table;
- B. SELECT count(member_id) FROM my_table;
- C. SELECT count_if(member_id IS NULL) FROM my_table;
- D. SELECT count_null(member_id) FROM my_table;
- E. SELECT count(member_id) - count_null(member_id) FROM my_table;
정답:C
설명:
To return the number of null values in the member_id column, the best option is to use the count_if function, which counts the number of rows that satisfy a given condition. In this case, the condition is that the member_id column is null. The other options are either incorrect or not supported by Spark SQL. Option A will return the number of non-null values in the member_id column. Option B will not work because there is no count_null function in Spark SQL. Option D will not work because there is no null function in Spark SQL. Option E will not work because there is no count_null function in Spark SQL. Reference:
Built-in Functions - Spark SQL, Built-in Functions
count_if - Spark SQL, Built-in Functions
질문 # 305
A company sells products across multiple categories (e.g., Electronics, Clothing) and regions.
The sales team has provided you with a PySpark dataframe named sales_df as below, and the team wants the data engineer to analyze the sales data to help make strategic decisions.
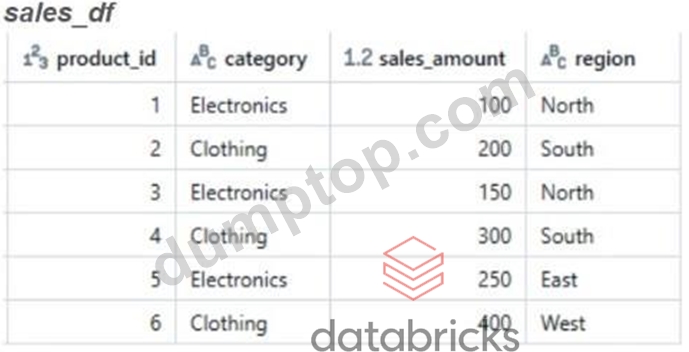
Calculate the total sales amount for each region and store the results in a new dataframe called region_sales.
Given the expected result:
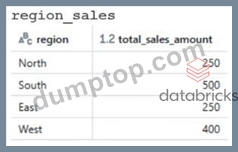
Which code will generate the expected result?
- A. region_sales = sales_df.groupBy("region").agg(sum("sales_amount").alias("total_sales_amount"))
- B. region_sales = sales_df.sum("sales_amount").groupBy("region").alias("total_sales_amount")
- C. region_sales = sales_df.agg(sum("sales_amount").groupBy("region").alias("total_sales_amount"))
- D. region_sales = sales_df.groupBy("category").sum("sales_amount").alias("total_sales_amount")
정답:A
설명:
To calculate total sales per region, you group by "region" and apply an aggregation using sum("sales_amount"), aliasing it as total_sales_amount. This produces the expected result of 250 (North), 500 (South), 250 (East), and 400 (West).
질문 # 306
A data engineer is setting up a new Databricks pipeline that ingests clickstream events from Kafka and daily product catalogs from cloud object storage. To ensure auditability and easy reprocessing, the engineer wants to land all source data first. Later stages will handle cleaning, deduplication, and business modeling before the data is used in dashboards.
Which approach aligns with Medallion Architecture principles?
- A. Land streaming events from Kafka in Silver and the product catalog directly in Gold to minimize layers for batch data
- B. Land both sources in the Bronze layer append-only with minimal validation, then build Silver/Gold downstream for quality and analytics
- C. Land both sources in Gold with denormalized star schemas to optimize BI while retaining full source fidelity
- D. Land both sources directly into the Silver layer with schema enforcement and deduplication to reduce downstream complexity
정답:B
설명:
Databricks describes the Bronze layer in the Medallion Architecture as the raw ingestion layer , where source data is landed with minimal validation or transformation so that the original records are preserved for auditability and reprocessing. This is especially important for sources like Kafka clickstream events and file-based product catalogs, because downstream logic such as cleansing, deduplication, conformance, and business modeling should happen later in Silver and Gold layers. Bronze data is commonly stored in an append-only pattern and may include basic ingestion metadata, but it should not be heavily transformed at this stage. Databricks explicitly recommends limiting cleanup and validation in Bronze and using Silver for validation and deduplication. That makes option C the best match to Databricks guidance. Options A, B, and D all skip or misuse the Bronze layer, which reduces traceability and makes recovery or replay harder if business logic changes later.
=========
질문 # 307
......
DumpTOP의 경험이 풍부한 전문가들이Databricks Databricks-Certified-Data-Engineer-Associate인증시험관련자료들을 계획적으로 페펙트하게 만들었습니다.Databricks Databricks-Certified-Data-Engineer-Associate인증시험응시에는 딱 좋은 자료들입니다. DumpTOP는 최고의 덤프만 제공합니다. 응시 전Databricks Databricks-Certified-Data-Engineer-Associate인증시험덤프로 최고의 시험대비준비를 하시기 바랍니다.
Databricks-Certified-Data-Engineer-Associate최신버전 시험덤프문제: https://www.dumptop.com/Databricks/Databricks-Certified-Data-Engineer-Associate-dump.html
- Databricks-Certified-Data-Engineer-Associate퍼펙트 덤프자료 🎩 Databricks-Certified-Data-Engineer-Associate최신버전 공부자료 🤩 Databricks-Certified-Data-Engineer-Associate시험패스 가능한 공부하기 🐘 { www.koreadumps.com }을(를) 열고《 Databricks-Certified-Data-Engineer-Associate 》를 검색하여 시험 자료를 무료로 다운로드하십시오Databricks-Certified-Data-Engineer-Associate덤프최신버전
- Databricks-Certified-Data-Engineer-Associate최고품질 예상문제모음 😋 Databricks-Certified-Data-Engineer-Associate높은 통과율 인기 덤프자료 ✅ Databricks-Certified-Data-Engineer-Associate높은 통과율 공부자료 🏳 《 www.itdumpskr.com 》에서 검색만 하면《 Databricks-Certified-Data-Engineer-Associate 》를 무료로 다운로드할 수 있습니다Databricks-Certified-Data-Engineer-Associate높은 통과율 시험덤프공부
- Databricks-Certified-Data-Engineer-Associate시험패스 인증공부 🦥 Databricks-Certified-Data-Engineer-Associate높은 통과율 시험덤프공부 🚶 Databricks-Certified-Data-Engineer-Associate최신버전 인기덤프 🔑 ▷ www.pass4test.net ◁은[ Databricks-Certified-Data-Engineer-Associate ]무료 다운로드를 받을 수 있는 최고의 사이트입니다Databricks-Certified-Data-Engineer-Associate높은 통과율 인기 시험자료
- Databricks-Certified-Data-Engineer-Associate인기자격증 덤프문제 덤프공부자료 😍 지금➥ www.itdumpskr.com 🡄에서{ Databricks-Certified-Data-Engineer-Associate }를 검색하고 무료로 다운로드하세요Databricks-Certified-Data-Engineer-Associate시험패스 가능한 인증덤프자료
- Databricks-Certified-Data-Engineer-Associate인기자격증 덤프문제 덤프는 PDF,테스트엔진,온라인버전 세가지 버전으로 제공 🛂 무료로 쉽게 다운로드하려면《 www.pass4test.net 》에서⮆ Databricks-Certified-Data-Engineer-Associate ⮄를 검색하세요Databricks-Certified-Data-Engineer-Associate높은 통과율 공부자료
- Databricks-Certified-Data-Engineer-Associate최고품질 덤프데모 다운로드 ☸ Databricks-Certified-Data-Engineer-Associate최신버전 인기덤프 🤙 Databricks-Certified-Data-Engineer-Associate최고품질 인증시험 기출자료 💛 ✔ www.itdumpskr.com ️✔️을(를) 열고➽ Databricks-Certified-Data-Engineer-Associate 🢪를 입력하고 무료 다운로드를 받으십시오Databricks-Certified-Data-Engineer-Associate시험패스 인증공부
- Databricks-Certified-Data-Engineer-Associate높은 통과율 인기 시험자료 🤺 Databricks-Certified-Data-Engineer-Associate높은 통과율 시험덤프공부 👄 Databricks-Certified-Data-Engineer-Associate최고품질 덤프데모 다운로드 🍌 ➥ www.dumptop.com 🡄에서✔ Databricks-Certified-Data-Engineer-Associate ️✔️를 검색하고 무료로 다운로드하세요Databricks-Certified-Data-Engineer-Associate덤프최신버전
- Databricks-Certified-Data-Engineer-Associate인기자격증 덤프문제 최신 인기시험 공부문제 👾 ➥ www.itdumpskr.com 🡄을(를) 열고✔ Databricks-Certified-Data-Engineer-Associate ️✔️를 검색하여 시험 자료를 무료로 다운로드하십시오Databricks-Certified-Data-Engineer-Associate시험패스 가능한 인증덤프자료
- Databricks-Certified-Data-Engineer-Associate인기자격증 덤프문제 시험준비에 가장 좋은 최신 공부자료 🌍 ▶ www.koreadumps.com ◀웹사이트에서⇛ Databricks-Certified-Data-Engineer-Associate ⇚를 열고 검색하여 무료 다운로드Databricks-Certified-Data-Engineer-Associate퍼펙트 공부
- Databricks-Certified-Data-Engineer-Associate인기자격증 덤프문제 100% 유효한 덤프공부자료 🔑 ( www.itdumpskr.com )에서➥ Databricks-Certified-Data-Engineer-Associate 🡄를 검색하고 무료 다운로드 받기Databricks-Certified-Data-Engineer-Associate최신버전 공부자료
- Databricks-Certified-Data-Engineer-Associate인기자격증 덤프문제 100% 유효한 덤프자료 🔳 ⮆ www.passtip.net ⮄은⮆ Databricks-Certified-Data-Engineer-Associate ⮄무료 다운로드를 받을 수 있는 최고의 사이트입니다Databricks-Certified-Data-Engineer-Associate최신버전 공부자료
-
www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.grepmed.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
그리고 DumpTOP Databricks-Certified-Data-Engineer-Associate 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1-Vb5jDaEPPHY6La98fDa38D5-uazPWf3


 icons at the top
right corner of the subsection.