Certified-Data-Engineer-Professional合格受験記, Certified-Data-Engineer-Professional試験番号, Certified-Data-Engineer-Professional認証資格, Certified-Data-Engineer-Professional関連日本語内容, Certified-Data-Engineer-Professional問題例

GoShikenというサイトは世界的に知名度が高いです。それはGoShikenが提供したIT業種のトレーニング資料の適用性が強いですから。それはGoShikenのIT専門家が長い時間で研究した成果です。彼らは自分の知識と経験を活かして、絶え間なく発展しているIT業種の状況によってGoShikenのDatabricksのCertified-Data-Engineer-Professionalトレーニング資料を作成したのです。多くの受験生が利用してからとても良い結果を反映しました。もしあなたはIT認証試験に準備している一人でしたら、GoShikenのDatabricksのCertified-Data-Engineer-Professional「Databricks Certified Data Engineer Professional」トレーニング資料を選らんだほうがいいです。利用しないのならメリットが分からないですから、速く使ってみてください。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section |
Weight |
Objectives |
| Topic 1: Data Sharing and Federation |
~8% |
- Configure Delta Sharing and Lakehouse Federation
|
| Topic 2: Monitoring, Logging, and Troubleshooting |
~8% |
- Use Spark UI, Query Profiler, and system tables
- Diagnose common pipeline and job failures
|
| Topic 3: Cost and Performance Optimization |
~13% |
- Optimize queries, clusters, and storage
- Leverage system tables and observability tools
|
| Topic 4: Data Modeling |
~10% |
- Apply dimensional modeling techniques
- Design scalable Delta Lake schemas and clustering
|
| Topic 5: Security and Governance |
~10% |
- Implement row-level security, column masking, and compliance
- Manage Unity Catalog permissions and ACLs
|
| Topic 6: Streaming Workloads and Change Data Capture |
~11% |
- Implement reliable streaming pipelines
- Apply AUTO CDC APIs and exactly-once semantics
|
| Topic 7: Developing Code for Data Processing using Python and SQL |
~22% |
- Manage dependencies, libraries, and UDFs
- Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
- Implement scalable Python/SQL code and project structures
|
| Topic 8: CI/CD, Testing, and Deployment |
~6% |
- Implement testing and deployment pipelines
- Deploy with Declarative Automation Bundles, CLI, and REST API
|
| Topic 9: Data Transformation, Cleansing, and Quality |
~12% |
- Apply advanced Spark transformations
- Enforce data quality and quarantine bad data
|
>> Certified-Data-Engineer-Professional合格受験記 <<
Certified-Data-Engineer-Professional試験番号、Certified-Data-Engineer-Professional認証資格
一部の候補者は、自社のCertified-Data-Engineer-Professionalソフトウェアテストシミュレーターを購入する場合があります。 ソフトバージョンをインストールできるパーソナルコンピューターの台数を尋ねられます。 実際、コンピューターの数に制限はありません。 したがって、Certified-Data-Engineer-Professionalソフトウェアテストシミュレータを購入すると、同時にマルチユーザーをサポートします。 無制限にコンピューターにインストールできます。 あなたが訓練学校である場合、教師が気軽に発表して説明するのに適しています。 優れたCertified-Data-Engineer-Professionalソフトウェアテストシミュレータは合格率が高く、GoShikenは長期的な協力をお待ちしています。
Databricks Certified Data Engineer Professional 認定 Certified-Data-Engineer-Professional 試験問題 (Q180-Q185):
質問 # 180
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs Ul. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic. What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
- A. Can Read
- B. Can edit
- C. Can run
- D. Can manage
正解:A
解説:
Granting a user 'Can Read' permissions on a notebook within Databricks allows them to view the notebook's content without the ability to execute or edit it. This level of permission ensures that the new team member can review the production logic for learning or auditing purposes without the risk of altering the notebook's code or affecting production data and workflows. This approach aligns with best practices for maintaining security and integrity in production environments, where strict access controls are essential to prevent unintended modifications.
質問 # 181
A data engineer is analyzing transactional data in a PySpark DataFrame df containing customer_id, transaction_timestamp (precise to milliseconds), and amount_spent. The objective is to compute a cumulative sum of amount_spent per customer, strictly ordered by transaction_timestamp. The cumulative sum must include all transactions from the earliest timestamp up to and including the current row, respecting temporal ordering within each customer partition. Which PySpark code snippet most accurately constructs the appropriate window specification and applies the aggregation to yield the correct cumulative expenditure per customer?
正解:B
解説:
This window specification partitions the data by customer_id, orders transactions by transaction_timestamp, and defines the frame from the first transaction through the current one.
This guarantees that the cumulative sum is computed independently per customer and strictly follows the temporal order, including all prior transactions up to the current row.
質問 # 182
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.
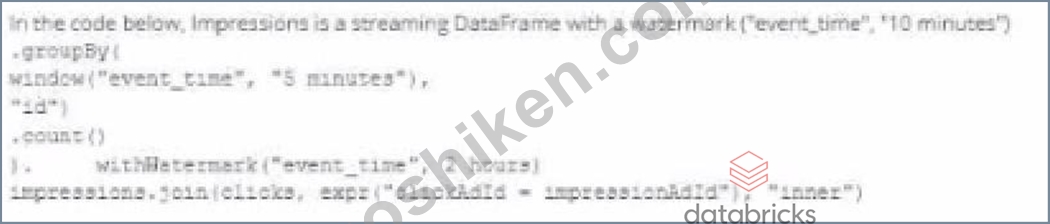
Which solution would improve the performance?
正解:D
解説:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
質問 # 183
A data engineering team is collaborating on a Databricks project where each team member needs to develop and test code independently before merging changes into the main branch.
They want to avoid accidental overwrites or branch switching issues while ensuring that all work is version- controlled and can be integrated into their CI/CD pipeline.
How should the data engineer achieve collaboration?
- A. All team members work in the same Databricks Git folder and perform Git operations (pull, push, commit, branch switching) directly in that shared folder.
- B. Team members edit notebooks directly in the workspace's shared folder and periodically copy changes into a Git folder for version control.
- C. Each team member creates their own Databricks Git folder, mapped to the same remote Git repository, and works in their own development branch within their personal folder.
- D. Team members use the Databricks CLI to clone the Git repository and perform Git operations from a cluster's web terminal.
正解:C
解説:
Using separate Databricks Git folders per user mapped to the same remote repository allows each team member to work independently on their own branch without interfering with others.
This prevents accidental overwrites or branch conflicts while ensuring all changes are version- controlled and easily integrated into CI/CD workflows.
質問 # 184
When evaluating the Ganglia Metrics for a given cluster with 3 executor nodes, which indicator would signal proper utilization of the VM's resources?
- A. CPU Utilization is around 75%
- B. Bytes Received never exceeds 80 million bytes per second
- C. Total Disk Space remains constant
- D. Network I/O never spikes
- E. The five Minute Load Average remains consistent/flat
正解:A
解説:
In the context of cluster performance and resource utilization, a CPU utilization rate of around
75% is generally considered a good indicator of efficient resource usage. This level of CPU utilization suggests that the cluster is being effectively used without being overburdened or underutilized. A consistent 75% CPU utilization indicates that the cluster's processing power is being effectively employed while leaving some headroom to handle spikes in workload or additional tasks without maxing out the CPU, which could lead to performance degradation. A five Minute Load Average that remains consistent/flat (Option A) might indicate underutilization or a bottleneck elsewhere.
Monitoring network I/O (Options B and C) is important, but these metrics alone don't provide a complete picture of resource utilization efficiency.
Total Disk Space (Option D) remaining constant is not necessarily an indicator of proper resource utilization, as it's more related to storage rather than computational efficiency.
質問 # 185
......
私たちの会社GoShikenは、10年以上にわたり、Certified-Data-Engineer-Professionalテスト準備の開発と改善に重点を置いてきました。そのため、Certified-Data-Engineer-Professional試験の同様のコンテンツ資料のステレオタイプを勇敢に打ち破りつつ、Certified-Data-Engineer-Professional試験ガイドに試験の真の内容を追加しています。ですから、私たちは、おざなりな態度よりも助けを提供するという強い態度を持っています。最短時間でCertified-Data-Engineer-Professional試験に合格するのに役立ちます。
Certified-Data-Engineer-Professional試験番号: https://www.goshiken.com/Databricks/Certified-Data-Engineer-Professional-mondaishu.html
- Certified-Data-Engineer-Professional復習過去問 🍫 Certified-Data-Engineer-Professional試験対応 🥠 Certified-Data-Engineer-Professionalミシュレーション問題 🧢 ➠ www.passtest.jp 🠰を開き、✔ Certified-Data-Engineer-Professional ️✔️を入力して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional勉強ガイド
- Certified-Data-Engineer-Professional試験の準備方法|最新のCertified-Data-Engineer-Professional合格受験記試験|ハイパスレートのDatabricks Certified Data Engineer Professional試験番号 ⬅️ 今すぐ{ www.goshiken.com }で▷ Certified-Data-Engineer-Professional ◁を検索して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional試験感想
- 有難いCertified-Data-Engineer-Professional|正確的なCertified-Data-Engineer-Professional合格受験記試験|試験の準備方法Databricks Certified Data Engineer Professional試験番号 👕 【 www.mogiexam.com 】にて限定無料の➡ Certified-Data-Engineer-Professional ️⬅️問題集をダウンロードせよCertified-Data-Engineer-Professional関連日本語内容
- 権威のある-有効的なCertified-Data-Engineer-Professional合格受験記試験-試験の準備方法Certified-Data-Engineer-Professional試験番号 🍔 ▷ www.goshiken.com ◁サイトにて最新⏩ Certified-Data-Engineer-Professional ⏪問題集をダウンロードCertified-Data-Engineer-Professional認定試験
- Certified-Data-Engineer-Professional試験感想 🎮 Certified-Data-Engineer-Professional勉強ガイド 👿 Certified-Data-Engineer-Professional試験対策 🍤 ( www.mogiexam.com )サイトにて最新▶ Certified-Data-Engineer-Professional ◀問題集をダウンロードCertified-Data-Engineer-Professional試験準備
- Certified-Data-Engineer-Professional試験の準備方法|真実的なCertified-Data-Engineer-Professional合格受験記試験|最新のDatabricks Certified Data Engineer Professional試験番号 👾 「 www.goshiken.com 」を入力して➤ Certified-Data-Engineer-Professional ⮘を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professionalテスト対策書
- Certified-Data-Engineer-Professional関連日本語内容 🏞 Certified-Data-Engineer-Professional勉強ガイド 👣 Certified-Data-Engineer-Professional受験方法 🦊 ☀ www.passtest.jp ️☀️サイトで⮆ Certified-Data-Engineer-Professional ⮄の最新問題が使えるCertified-Data-Engineer-Professionalテスト対策書
- 権威のある-有効的なCertified-Data-Engineer-Professional合格受験記試験-試験の準備方法Certified-Data-Engineer-Professional試験番号 🍷 ➠ www.goshiken.com 🠰で➥ Certified-Data-Engineer-Professional 🡄を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional無料サンプル
- 試験の準備方法-実用的なCertified-Data-Engineer-Professional合格受験記試験-最高のCertified-Data-Engineer-Professional試験番号 🐐 ➽ www.jptestking.com 🢪から▶ Certified-Data-Engineer-Professional ◀を検索して、試験資料を無料でダウンロードしてくださいCertified-Data-Engineer-Professional受験方法
- 試験の準備方法-最新のCertified-Data-Engineer-Professional合格受験記試験-高品質なCertified-Data-Engineer-Professional試験番号 🤺 「 www.goshiken.com 」を開き、( Certified-Data-Engineer-Professional )を入力して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional試験勉強攻略
- Certified-Data-Engineer-Professional試験の準備方法 | 有難いCertified-Data-Engineer-Professional合格受験記試験 | 真実的なDatabricks Certified Data Engineer Professional試験番号 🤤 ⇛ www.japancert.com ⇚を入力して▶ Certified-Data-Engineer-Professional ◀を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional勉強ガイド
-
www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.bandlab.com, www.stes.tyc.edu.tw, faithlife.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes


 icons at the top
right corner of the subsection.