Certified-Data-Engineer-Professional높은 통과율 인기 시험자료, Certified-Data-Engineer-Professional최신 업데이트 시험대비자료, Certified-Data-Engineer-Professional시험패스 가능한 공부문제, Certified-Data-Engineer-Professional최신버전 인기 시험자료, Certified-Data-Engineer-Professional합격보장 가능 덤프공부

Databricks인증Certified-Data-Engineer-Professional시험은 IT인증시험과목중 가장 인기있는 시험입니다. Itcertkr에서는Databricks인증Certified-Data-Engineer-Professional시험에 대비한 공부가이드를 발췌하여 IT인사들의 시험공부 고민을 덜어드립니다. Itcertkr에서 발췌한 Databricks인증Certified-Data-Engineer-Professional덤프는 실제시험의 모든 범위를 커버하고 있고 모든 시험유형이 포함되어 있어 시험준비 공부의 완벽한 선택입니다.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section |
Weight |
Objectives |
| Data Transformation, Cleansing, and Quality |
~12% |
- Enforce data quality and quarantine bad data
- Apply advanced Spark transformations
|
| Data Sharing and Federation |
~8% |
- Configure Delta Sharing and Lakehouse Federation
|
| CI/CD, Testing, and Deployment |
~6% |
- Deploy with Declarative Automation Bundles, CLI, and REST API
- Implement testing and deployment pipelines
|
| Monitoring, Logging, and Troubleshooting |
~8% |
- Use Spark UI, Query Profiler, and system tables
- Diagnose common pipeline and job failures
|
| Security and Governance |
~10% |
- Manage Unity Catalog permissions and ACLs
- Implement row-level security, column masking, and compliance
|
| Cost and Performance Optimization |
~13% |
- Optimize queries, clusters, and storage
- Leverage system tables and observability tools
|
| Data Modeling |
~10% |
- Apply dimensional modeling techniques
- Design scalable Delta Lake schemas and clustering
|
| Streaming Workloads and Change Data Capture |
~11% |
- Implement reliable streaming pipelines
- Apply AUTO CDC APIs and exactly-once semantics
|
| Developing Code for Data Processing using Python and SQL |
~22% |
- Implement scalable Python/SQL code and project structures
- Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
- Manage dependencies, libraries, and UDFs
|
>> Certified-Data-Engineer-Professional높은 통과율 인기 시험자료 <<
Certified-Data-Engineer-Professional최신 업데이트 시험대비자료 - Certified-Data-Engineer-Professional시험패스 가능한 공부문제
Itcertkr의Databricks인증 Certified-Data-Engineer-Professional덤프는 인터넷에서 검색되는Databricks인증 Certified-Data-Engineer-Professional시험공부자료중 가장 출중한 시험준비 자료입니다. Databricks인증 Certified-Data-Engineer-Professional덤프를 공부하면 시험패스는 물론이고 IT지식을 더 많이 쌓을수 있어 일거량득입니다.자격증을 취득하여 자신있게 승진하여 연봉협상하세요.
최신 Databricks Certification Certified-Data-Engineer-Professional 무료샘플문제 (Q102-Q107):
질문 # 102
The following code has been migrated to a Databricks notebook from a legacy workload:
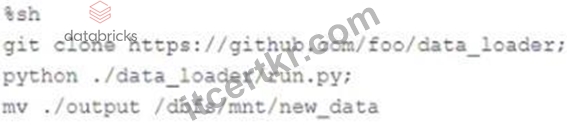
The code executes successfully and provides the logically correct results, however, it takes over
20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
- B. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
- C. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- D. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- E. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
정답:C
설명:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
질문 # 103
Which statement describes the default execution mode for Databricks Auto Loader?
- A. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; the target table is materialized by directly querying all valid files in the source directory.
- B. Cloud vendor-specific queue storage and notification services are configured to track newly arriving files; new files are incrementally and impotently into the target Delta Lake table.
- C. New files are identified by listing the input directory; new files are incrementally and idempotently loaded into the target Delta Lake table.
- D. Webhook trigger Databricks job to run anytime new data arrives in a source directory; new data automatically merged into target tables using rules inferred from the data.
- E. New files are identified by listing the input directory; the target table is materialized by directory querying all valid files in the source directory.
정답:C
설명:
Databricks Auto Loader simplifies and automates the process of loading data into Delta Lake.
The default execution mode of the Auto Loader identifies new files by listing the input directory. It incrementally and idempotently loads these new files into the target Delta Lake table. This approach ensures that files are not missed and are processed exactly once, avoiding data duplication. The other options describe different mechanisms or integrations that are not part of the default behavior of the Auto Loader.
질문 # 104
A user new to Databricks is trying to troubleshoot long execution times for some pipeline logic they are working on. Presently, the user is executing code cell-by-cell, using display() calls to confirm code is producing the logically correct results as new transformations are added to an operation. To get a measure of average time to execute, the user is running each cell multiple times interactively.
Which of the following adjustments will get a more accurate measure of how code is likely to perform in production?
- A. Calling display () forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results.
- B. The Jobs Ul should be leveraged to occasionally run the notebook as a job and track execution time during incremental code development because Photon can only be enabled on clusters launched for scheduled jobs.
- C. The only way to meaningfully troubleshoot code execution times in development notebooks Is to use production-sized data and production-sized clusters with Run All execution.
- D. Scala is the only language that can be accurately tested using interactive notebooks; because the best performance is achieved by using Scala code compiled to JARs. all PySpark and Spark SQL logic should be refactored.
- E. Production code development should only be done using an IDE; executing code against a local build of open source Spark and Delta Lake will provide the most accurate benchmarks for how code will perform in production.
정답:C
질문 # 105
A data engineer is implementing a job to download multiple PDF files from a third-party provided REST API endpoint by specifying different report types. The REST API is time-consuming and encounters intermittent errors, so the engineer wants to track each download activity to know when it fails and to retry partially, while providing scalable throughput. The engineer needs to download ten report types, and the list can be changed over time. How should the data engineer achieve this?
- A. Use a Delta Lake table to track each report download status as 10 rows, and use it as a source table to execute the download function as a Pandas UDF.
- B. Use a foreach task with a list of report types as its inputs.
- C. Define ten Notebook tasks to clearly track which report download failed.
- D. Define a list variable within a Notebook to loop through the report types to download them, and print the download results. Execute it as a Notebook tasks.
정답:B
설명:
A foreach task allows the job to dynamically iterate over a configurable list of report types, execute downloads in parallel, and track the success or failure of each item independently. This enables scalable throughput, partial retries for failed downloads, and easy updates when the list of report types changes, without hardcoding tasks or introducing unnecessary complexity.
질문 # 106
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the field pk_id.
For analytical purposes, only the most recent value for each record needs to be recorded in the target Delta Lake table in the Lakehouse. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
- A. Deduplicate records in each batch by pk_id and overwrite the target table.
- B. Use MERGE INTO to insert, update, or delete the most recent entry for each pk_id into a table, then propagate all changes throughout the system.
- C. Iterate through an ordered set of changes to the table, applying each in turn to create the current state of the table, (insert, update, delete), timestamp of change, and the values.
- D. Use Delta Lake's change data feed to automatically process CDC data from an external system, propagating all changes to all dependent tables in the Lakehouse.
정답:D
질문 # 107
......
Itcertkr에서 최고최신버전의Databricks인증Certified-Data-Engineer-Professional시험덤프 즉 문제와 답을 받으실 수 있습니다. 빨리 소지한다면 좋겠죠. 그래야 여러분은 빨리 한번에Databricks인증Certified-Data-Engineer-Professional시험을 패스하실 수 있습니다.Databricks인증Certified-Data-Engineer-Professional관련 최고의 자료는 현재까지는Itcertkr덤프가 최고라고 자신 있습니다.
Certified-Data-Engineer-Professional최신 업데이트 시험대비자료: https://www.itcertkr.com/Certified-Data-Engineer-Professional_exam.html
- 100% 유효한 Certified-Data-Engineer-Professional높은 통과율 인기 시험자료 시험덤프 ⬛ 무료로 쉽게 다운로드하려면【 www.exampassdump.com 】에서( Certified-Data-Engineer-Professional )를 검색하세요Certified-Data-Engineer-Professional퍼펙트 인증공부
- Certified-Data-Engineer-Professional시험대비 덤프공부 ❤ Certified-Data-Engineer-Professional인기자격증 덤프공부자료 🧑 Certified-Data-Engineer-Professional시험패스 가능 덤프 🤏 ▷ www.itdumpskr.com ◁의 무료 다운로드➤ Certified-Data-Engineer-Professional ⮘페이지가 지금 열립니다Certified-Data-Engineer-Professional시험대비 덤프공부
- Certified-Data-Engineer-Professional높은 통과율 인기 시험자료 인증시험정보 🏀 지금▷ www.pass4test.net ◁에서( Certified-Data-Engineer-Professional )를 검색하고 무료로 다운로드하세요Certified-Data-Engineer-Professional최신시험
- Certified-Data-Engineer-Professional높은 통과율 인기 시험자료 인증시험 🦮 ⏩ www.itdumpskr.com ⏪을(를) 열고⏩ Certified-Data-Engineer-Professional ⏪를 입력하고 무료 다운로드를 받으십시오Certified-Data-Engineer-Professional최고덤프데모
- Certified-Data-Engineer-Professional시험패스 가능 공부자료 🪀 Certified-Data-Engineer-Professional최신시험 😠 Certified-Data-Engineer-Professional최고덤프데모 📷 무료 다운로드를 위해{ Certified-Data-Engineer-Professional }를 검색하려면[ kr.fast2test.com ]을(를) 입력하십시오Certified-Data-Engineer-Professional시험패스 가능 덤프
- Certified-Data-Engineer-Professional높은 통과율 인기 시험자료 인증시험 🦉 { www.itdumpskr.com }에서《 Certified-Data-Engineer-Professional 》를 검색하고 무료 다운로드 받기Certified-Data-Engineer-Professional 100%시험패스 덤프문제
- Certified-Data-Engineer-Professional시험대비 덤프공부 🐼 Certified-Data-Engineer-Professional최고덤프데모 🚞 Certified-Data-Engineer-Professional퍼펙트 덤프자료 🅾 무료로 다운로드하려면【 kr.fast2test.com 】로 이동하여「 Certified-Data-Engineer-Professional 」를 검색하십시오Certified-Data-Engineer-Professional최신버전 덤프데모문제
- 100% 유효한 Certified-Data-Engineer-Professional높은 통과율 인기 시험자료 시험덤프 🏛 ➡ www.itdumpskr.com ️⬅️을(를) 열고「 Certified-Data-Engineer-Professional 」를 입력하고 무료 다운로드를 받으십시오Certified-Data-Engineer-Professional최고덤프데모
- Certified-Data-Engineer-Professional 100%시험패스 덤프 👓 Certified-Data-Engineer-Professional인기자격증 덤프공부자료 🧾 Certified-Data-Engineer-Professional시험대비 덤프 최신 데모 ⬅️ 시험 자료를 무료로 다운로드하려면☀ kr.fast2test.com ️☀️을 통해➡ Certified-Data-Engineer-Professional ️⬅️를 검색하십시오Certified-Data-Engineer-Professional시험패스 가능 공부자료
- Certified-Data-Engineer-Professional높은 통과율 인기 시험자료 덤프샘플문제 다운로드 🎯 ▷ www.itdumpskr.com ◁웹사이트에서▛ Certified-Data-Engineer-Professional ▟를 열고 검색하여 무료 다운로드Certified-Data-Engineer-Professional퍼펙트 인증공부
- Certified-Data-Engineer-Professional시험패스 가능 공부자료 🏺 Certified-Data-Engineer-Professional시험대비 덤프공부 ☔ Certified-Data-Engineer-Professional 100%시험패스 덤프 🔭 검색만 하면▷ kr.fast2test.com ◁에서▛ Certified-Data-Engineer-Professional ▟무료 다운로드Certified-Data-Engineer-Professional퍼펙트 인증공부
-
link.woomy.me, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, gettr.com, freestyler.ws, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes


 icons at the top
right corner of the subsection.