Professional-Data-Engineer認證指南, 新版Professional-Data-Engineer題庫, Professional-Data-Engineer考題, Professional-Data-Engineer指南, Professional-Data-Engineer考古题推薦
順便提一下,可以從雲存儲中下載KaoGuTi Professional-Data-Engineer考試題庫的完整版:https://drive.google.com/open?id=1VIyWUb7UF2oRbqz5y0XSuMps_ttkb88U
你瞭解KaoGuTi的Professional-Data-Engineer考試考古題嗎?為什麼用過的人都讚不絕口呢?是不是很想試一試它是否真的那麼有效果?趕快點擊KaoGuTi的網站去下載吧,每個問題都有提供demo,覺得好用可以立即購買。你購買了考古題以後還可以得到一年的免費更新服務,一年之內,只要你想更新你擁有的資料,那麼你就可以得到最新版。有了這個資料你就能輕鬆通過Professional-Data-Engineer考試,獲得資格認證。
為了準備 Google Professional-Data-Engineer 考試,考生可以利用網路上許多資源。Google 提供多種培訓課程和學習材料,包括線上課程、練習考試和學習指南。此外,還有許多學習小組和論壇,考生可以與其他準備考試的專業人士聯繫。透過正確的準備和投入,專業人士可以獲得 Google 認證的專業資料工程師證書,並展示他們在 Google 雲端平台方面的專業知識。
>> Professional-Data-Engineer認證指南 <<
新版Google Professional-Data-Engineer題庫,Professional-Data-Engineer考題
KaoGuTi 應一些考友的需要,在第一時間內及時更新了 Professional-Data-Engineer 這門題目,更新之後的 Professional-Data-Engineer 擬真試題覆蓋率100%。考生可在反復練習這份真題的基礎上,多思考,多總結,通過 Professional-Data-Engineer 考試就沒有問題了。建議的是,一定要瞭解這門考試的最新動態資訊,這樣才能在考試中做到隨機應變。而我們就是一個可以滿足很多參加Google Professional-Data-Engineer 認證考試的IT人士的需求的網站。
Google Professional-DATA工程師認證的考試是一項全面且具有挑戰性的測試,涵蓋了與數據工程相關的廣泛主題。考試包括多選擇和基於方案的問題,這些問題要求候選人將其知識應用於現實世界情景。要求候選人在數據處理,數據分析,數據集成和數據可視化等領域中證明其專業知識。
獲得Google認證的專業數據工程師證書,向雇主和同事證明該個人具備在Google Cloud Platform上設計和構建數據處理系統所需的知識和技能。該認證可以打開新的職業機會,並幫助個人在其目前的角色中取得進展。
最新的 Google Cloud Certified Professional-Data-Engineer 免費考試真題 (Q141-Q146):
問題 #141
You work for a large ecommerce company. You are using Pub/Sub to ingest the clickstream data to Google Cloud for analytics. You observe that when a new subscriber connects to an existing topic to analyze data, they are unable to subscribe to older data for an upcoming yearly sale event in two months, you need a solution that, once implemented, will enable any new subscriber to read the last 30 days of data. What should you do?
- A. Set the topic retention policy to 30 days.
- B. Set the subscriber retention policy to 30 days.
- C. Ask the source system to re-push the data to Pub/Sub, and subscribe to it.
- D. Create a new topic, and publish the last 30 days of data each time a new subscriber connects to an existing topic.
答案:A
解題說明:
By setting the topic retention policy to 30 days, you can ensure that any new subscriber can access the messages that were published to the topic within the last 30 days1. This feature allows you to replay previously acknowledged messages or initialize new subscribers with historical data2. You can configure the topic retention policy by using the Cloud Console, the gcloud command-line tool, or the Pub/Sub API1.
Option A is not efficient, as it requires creating a new topic and duplicating the data for each new subscriber, which would increase the storage costs and complexity. Option C is not effective, as it only affects the unacknowledged messages in a subscription, and does not allow new subscribers to access older data3. Option D is not feasible, as it depends on the source system's ability and willingness to re-push the data, and it may cause data duplication or inconsistency. References:
* 1: Create a topic | Cloud Pub/Sub Documentation | Google Cloud
* 2: Replay and purge messages with seek | Cloud Pub/Sub Documentation | Google Cloud
* 3: When is a PubSub Subscription considered to be inactive?
問題 #142
The marketing team at your organization provides regular updates of a segment of your customer dataset. The marketing team has given you a CSV with 1 million records that must be updated in BigQuery. When you use the UPDATE statement in BigQuery, you receive a quotaExceeded error. What should you do?
- A. Reduce the number of records updated each day to stay within the BigQuery UPDATE DML statement limit.
- B. Increase the BigQuery UPDATE DML statement limit in the Quota management section of the Google Cloud Platform Console.
- C. Import the new records from the CSV file into a new BigQuery table. Create a BigQuery job that merges the new records with the existing records and writes the results to a new BigQuery table.
- D. Split the source CSV file into smaller CSV files in Cloud Storage to reduce the number of BigQuery UPDATE DML statements per BigQuery job.
答案:A
問題 #143
You have spent a few days loading data from comma-separated values (CSV) files into the Google BigQuery table CLICK_STREAM. The column DT stores the epoch time of click events. For convenience, you chose a simple schema where every field is treated as the STRING type. Now, you want to compute web session durations of users who visit your site, and you want to change its data type to the TIMESTAMP. You want to minimize the migration effort without making future queries computationally expensive. What should you do?
- A. Delete the table CLICK_STREAM, and then re-create it such that the column DT is of the TIMESTAMP type. Reload the data.
- B. Create a view CLICK_STREAM_V, where strings from the column DT are cast into TIMESTAMP values. Reference the view CLICK_STREAM_V instead of the table CLICK_STREAM from now on.
- C. Add two columns to the table CLICK STREAM: TS of the TIMESTAMP type and IS_NEW of the BOOLEAN type. Reload all data in append mode. For each appended row, set the value of IS_NEW to true. For future queries, reference the column TS instead of the column DT, with the WHERE clause ensuring that the value of IS_NEW must be true.
- D. Construct a query to return every row of the table CLICK_STREAM, while using the built-in function to cast strings from the column DT into TIMESTAMP values. Run the query into a destination table NEW_CLICK_STREAM, in which the column TS is the TIMESTAMP type. Reference the table NEW_CLICK_STREAM instead of the table CLICK_STREAM from now on. In the future, new data is loaded into the table NEW_CLICK_STREAM.
- E. Add a column TS of the TIMESTAMP type to the table CLICK_STREAM, and populate the numeric values from the column TS for each row. Reference the column TS instead of the column DT from now on.
答案:C
解題說明:
Topic 1, Flowlogistic Case Study
Company Overview
Flowlogistic is a leading logistics and supply chain provider. They help businesses throughout the world manage their resources and transport them to their final destination. The company has grown rapidly, expanding their offerings to include rail, truck, aircraft, and oceanic shipping.
Company Background
The company started as a regional trucking company, and then expanded into other logistics market. Because they have not updated their infrastructure, managing and tracking orders and shipments has become a bottleneck. To improve operations, Flowlogistic developed proprietary technology for tracking shipments in real time at the parcel level. However, they are unable to deploy it because their technology stack, based on Apache Kafka, cannot support the processing volume. In addition, Flowlogistic wants to further analyze their orders and shipments to determine how best to deploy their resources.
Solution Concept
Flowlogistic wants to implement two concepts using the cloud:
* Use their proprietary technology in a real-time inventory-tracking system that indicates the location of their loads
* Perform analytics on all their orders and shipment logs, which contain both structured and unstructured data, to determine how best to deploy resources, which markets to expand info. They also want to use predictive analytics to learn earlier when a shipment will be delayed.
Existing Technical Environment
Flowlogistic architecture resides in a single data center:
* Databases
* 8 physical servers in 2 clusters
* SQL Server - user data, inventory, static data
* 3 physical servers
* Cassandra - metadata, tracking messages
10 Kafka servers - tracking message aggregation and batch insert
* Application servers - customer front end, middleware for order/customs
* 60 virtual machines across 20 physical servers
* Tomcat - Java services
* Nginx - static content
* Batch servers
Storage appliances
* iSCSI for virtual machine (VM) hosts
* Fibre Channel storage area network (FC SAN) - SQL server storage
* Network-attached storage (NAS) image storage, logs, backups
* Apache Hadoop /Spark servers
* Core Data Lake
* Data analysis workloads
* 20 miscellaneous servers
* Jenkins, monitoring, bastion hosts,
Business Requirements
* Build a reliable and reproducible environment with scaled panty of production.
* Aggregate data in a centralized Data Lake for analysis
* Use historical data to perform predictive analytics on future shipments
* Accurately track every shipment worldwide using proprietary technology
* Improve business agility and speed of innovation through rapid provisioning of new resources
* Analyze and optimize architecture for performance in the cloud
* Migrate fully to the cloud if all other requirements are met
Technical Requirements
* Handle both streaming and batch data
* Migrate existing Hadoop workloads
* Ensure architecture is scalable and elastic to meet the changing demands of the company.
* Use managed services whenever possible
* Encrypt data flight and at rest
* Connect a VPN between the production data center and cloud environment SEO Statement We have grown so quickly that our inability to upgrade our infrastructure is really hampering further growth and efficiency. We are efficient at moving shipments around the world, but we are inefficient at moving data around.
We need to organize our information so we can more easily understand where our customers are and what they are shipping.
CTO Statement
IT has never been a priority for us, so as our data has grown, we have not invested enough in our technology. I have a good staff to manage IT, but they are so busy managing our infrastructure that I cannot get them to do the things that really matter, such as organizing our data, building the analytics, and figuring out how to implement the CFO' s tracking technology.
CFO Statement
Part of our competitive advantage is that we penalize ourselves for late shipments and deliveries. Knowing where out shipments are at all times has a direct correlation to our bottom line and profitability. Additionally, I don't want to commit capital to building out a server environment.
問題 #144
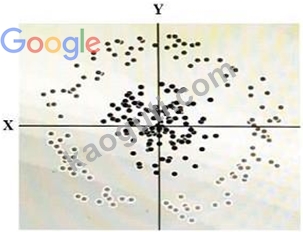
You have some data, which is shown in the graphic below. The two dimensions are X and Y, and the shade of each dot represents what class it is. You want to classify this data accurately using a linear algorithm. To do this you need to add a synthetic feature. What should the value of that feature be?
- A. cos(X)
- B. Y2
- C. X2+Y2
- D. X2
答案:C
問題 #145
Which of these are examples of a value in a sparse vector? (Select 2 answers.)
- A. [0, 0, 0, 1, 0, 0, 1]
- B. [1, 0, 0, 0, 0, 0, 0]
- C. [0, 5, 0, 0, 0, 0]
- D. [0, 1]
答案:B,D
解題說明:
Categorical features in linear models are typically translated into a sparse vector in which each possible value has a corresponding index or id. For example, if there are only three possible eye colors you can represent 'eye_color' as a length 3 vector: 'brown' would become [1, 0, 0], 'blue' would become [0, 1, 0] and 'green' would become [0, 0, 1]. These vectors are called "sparse" because they may be very long, with many zeros, when the set of possible values is very large (such as all English words).
[0, 0, 0, 1, 0, 0, 1] is not a sparse vector because it has two 1s in it. A sparse vector contains only a single 1.
[0, 5, 0, 0, 0, 0] is not a sparse vector because it has a 5 in it. Sparse vectors only contain 0s and 1s.
問題 #146
......
新版Professional-Data-Engineer題庫: https://kaoguti.com/Professional-Data-Engineer_exam-pdf.html
- Professional-Data-Engineer題庫更新資訊 🥳 Professional-Data-Engineer權威考題 💘 Professional-Data-Engineer題庫更新 🟫 打開網站☀ www.newdumpspdf.com ️☀️搜索➡ Professional-Data-Engineer ️⬅️免費下載Professional-Data-Engineer考古题推薦
- 最真實的Professional-Data-Engineer認證考試的參考資料 🌗 ➤ www.newdumpspdf.com ⮘最新➠ Professional-Data-Engineer 🠰問題集合Professional-Data-Engineer資料
- 最新Professional-Data-Engineer考古題 ⏬ Professional-Data-Engineer考古題更新 🛢 Professional-Data-Engineer考古題分享 🕺 立即在⏩ tw.fast2test.com ⏪上搜尋▷ Professional-Data-Engineer ◁並免費下載Professional-Data-Engineer題庫更新資訊
- 最新Professional-Data-Engineer考古題 📃 Professional-Data-Engineer考試資訊 🕖 新版Professional-Data-Engineer考古題 🏣 複製網址{ www.newdumpspdf.com }打開並搜索「 Professional-Data-Engineer 」免費下載Professional-Data-Engineer真題
- 最新Professional-Data-Engineer考證 🏰 Professional-Data-Engineer考古題分享 🐱 Professional-Data-Engineer真題 🔰 立即到▶ www.newdumpspdf.com ◀上搜索⇛ Professional-Data-Engineer ⇚以獲取免費下載最新Professional-Data-Engineer考證
- Professional-Data-Engineer考題免費下載 🧘 Professional-Data-Engineer題庫更新 🥖 Professional-Data-Engineer考題寶典 🏺 免費下載➤ Professional-Data-Engineer ⮘只需在▛ www.newdumpspdf.com ▟上搜索Professional-Data-Engineer考題免費下載
- 最新Professional-Data-Engineer考古題 ⬅️ Professional-Data-Engineer題庫更新資訊 📹 Professional-Data-Engineer題庫更新資訊 🏃 到✔ www.vcesoft.com ️✔️搜索[ Professional-Data-Engineer ]輕鬆取得免費下載最新Professional-Data-Engineer考證
- Professional-Data-Engineer熱門考題 🧐 新版Professional-Data-Engineer考古題 🦏 Professional-Data-Engineer考古題 🧳 到“ www.newdumpspdf.com ”搜索➤ Professional-Data-Engineer ⮘輕鬆取得免費下載最新Professional-Data-Engineer考證
- 最新Professional-Data-Engineer考證 🧄 最新Professional-Data-Engineer考證 🕯 Professional-Data-Engineer考題免費下載 👙 ➥ www.newdumpspdf.com 🡄上的免費下載[ Professional-Data-Engineer ]頁面立即打開Professional-Data-Engineer題庫更新
- 最真實的Professional-Data-Engineer認證考試的參考資料 🧍 進入【 www.newdumpspdf.com 】搜尋⮆ Professional-Data-Engineer ⮄免費下載Professional-Data-Engineer指南
- 最受推薦的Professional-Data-Engineer認證指南,免費下載Professional-Data-Engineer考試指南得到妳想要的Google證書 🎿 在➥ www.newdumpspdf.com 🡄上搜索⇛ Professional-Data-Engineer ⇚並獲取免費下載Professional-Data-Engineer權威考題
-
www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
2026 KaoGuTi最新的Professional-Data-Engineer PDF版考試題庫和Professional-Data-Engineer考試問題和答案免費分享:https://drive.google.com/open?id=1VIyWUb7UF2oRbqz5y0XSuMps_ttkb88U


 icons at the top
right corner of the subsection.